
Yuxuan Jiang
江宇轩I am Yuxuan Jiang (江宇轩), a PhD student at
Tsinghua University.
My research interests include multimodal learning, diffusion models,
and audio generation.
I study unified representations for speech, environmental sounds,
and music that capture acoustic details, semantic content, and temporal structure. I also explore
cross-modal and interaction-driven models that predict how sound evolves, enabling continuous and
controllable audio generation grounded in physical and structural priors.
I welcome conversations and collaborations on these and related topics, from informal exchanges to in-depth discussions. Please feel free to reach out by email.
News
- [2026.07] 🎉 One paper: CineDub: Scaling End-to-End Video Dubbing to Multi-Speaker Dialogues with Coherent Sound Effects accepted by ACM MM 2026.
- [2026.07] 🚀 Our real-time interactive video generation model is released on Vidu S1! I contributed to the speech-driven module and real-time voice interaction. The Technical Report is publicly available.
- [2026.06] 🎉 One paper: SR-Edit: Region-Aware Image Editing via Self-Refinement accepted by ECCV 2026.
- [2026.06] 🎉 One paper: FreeSonic: Training-Free Temporal-Aware Decoupled Attention for Precise Audio Editing accepted by Interspeech 2026.
- [2026.04] 🎉 One paper: ControlAudio: Tackling Text-Guided, Timing-Indicated and Intelligible Audio Generation via Progressive Diffusion Modeling accepted by ACL 2026 Main (Oral, top 15%).
- [2026.01] 🚀 Our joint video-audio generation model is released on Vidu Q3 ! I developed the high-fidelity 48 kHz stereo audio VAE that powers its audio generation.
- [2026.01] 🎉 One paper: Omni2Sound: Towards Unified Video-Text-to-Audio Generation accepted by CVPR 2026 (Highlight, top 15%).
- [2025.07] 🎉 One paper: FreeAudio: Training-Free Timing Planning for Controllable Long-Form Text-to-Audio Generation accepted by ACM MM 2025 (Oral).
- [2025.03] 🚀 Our text-to-audio model is released on Vidu Q1 ! I developed the text-to-audio and timing-controlled systems that power its audio generation capabilities.
Selected Publications
[ Google Scholar]
-
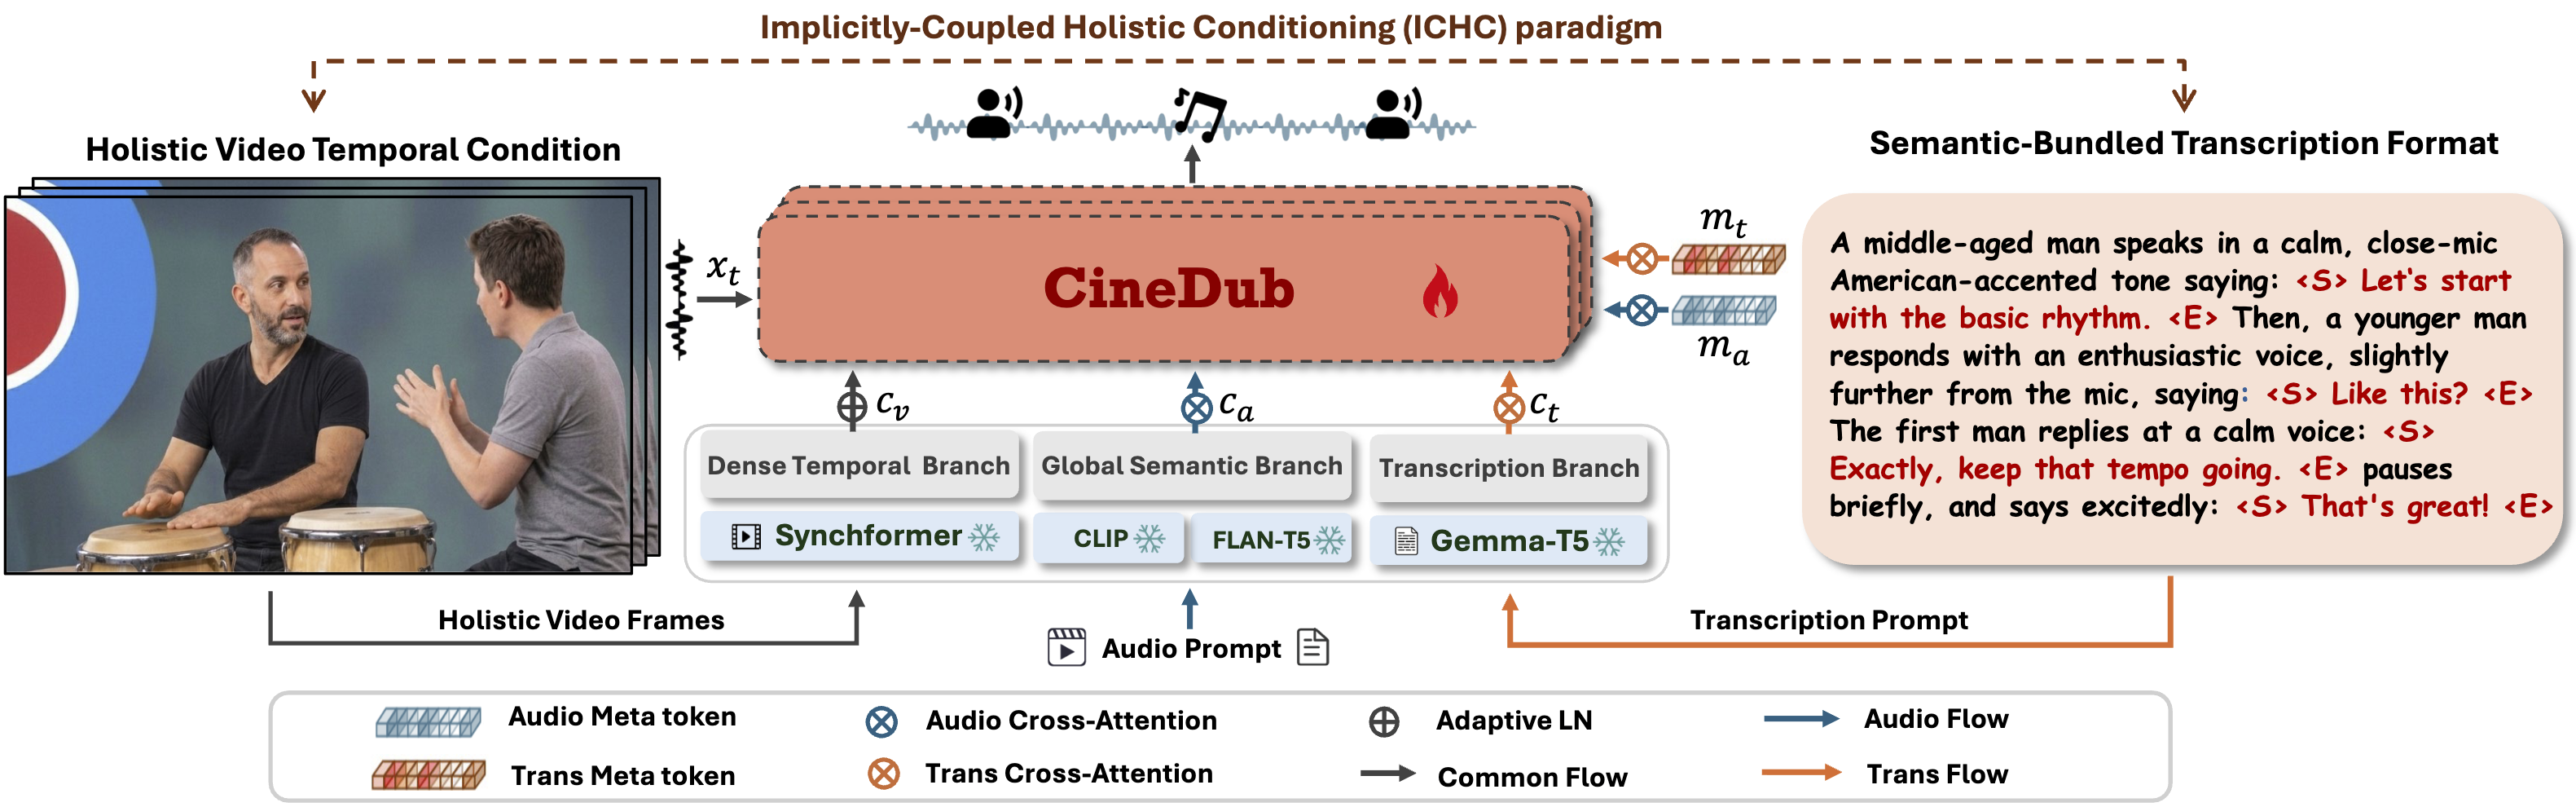 ACM International Conference on Multimedia (ACM MM), 2026.
-
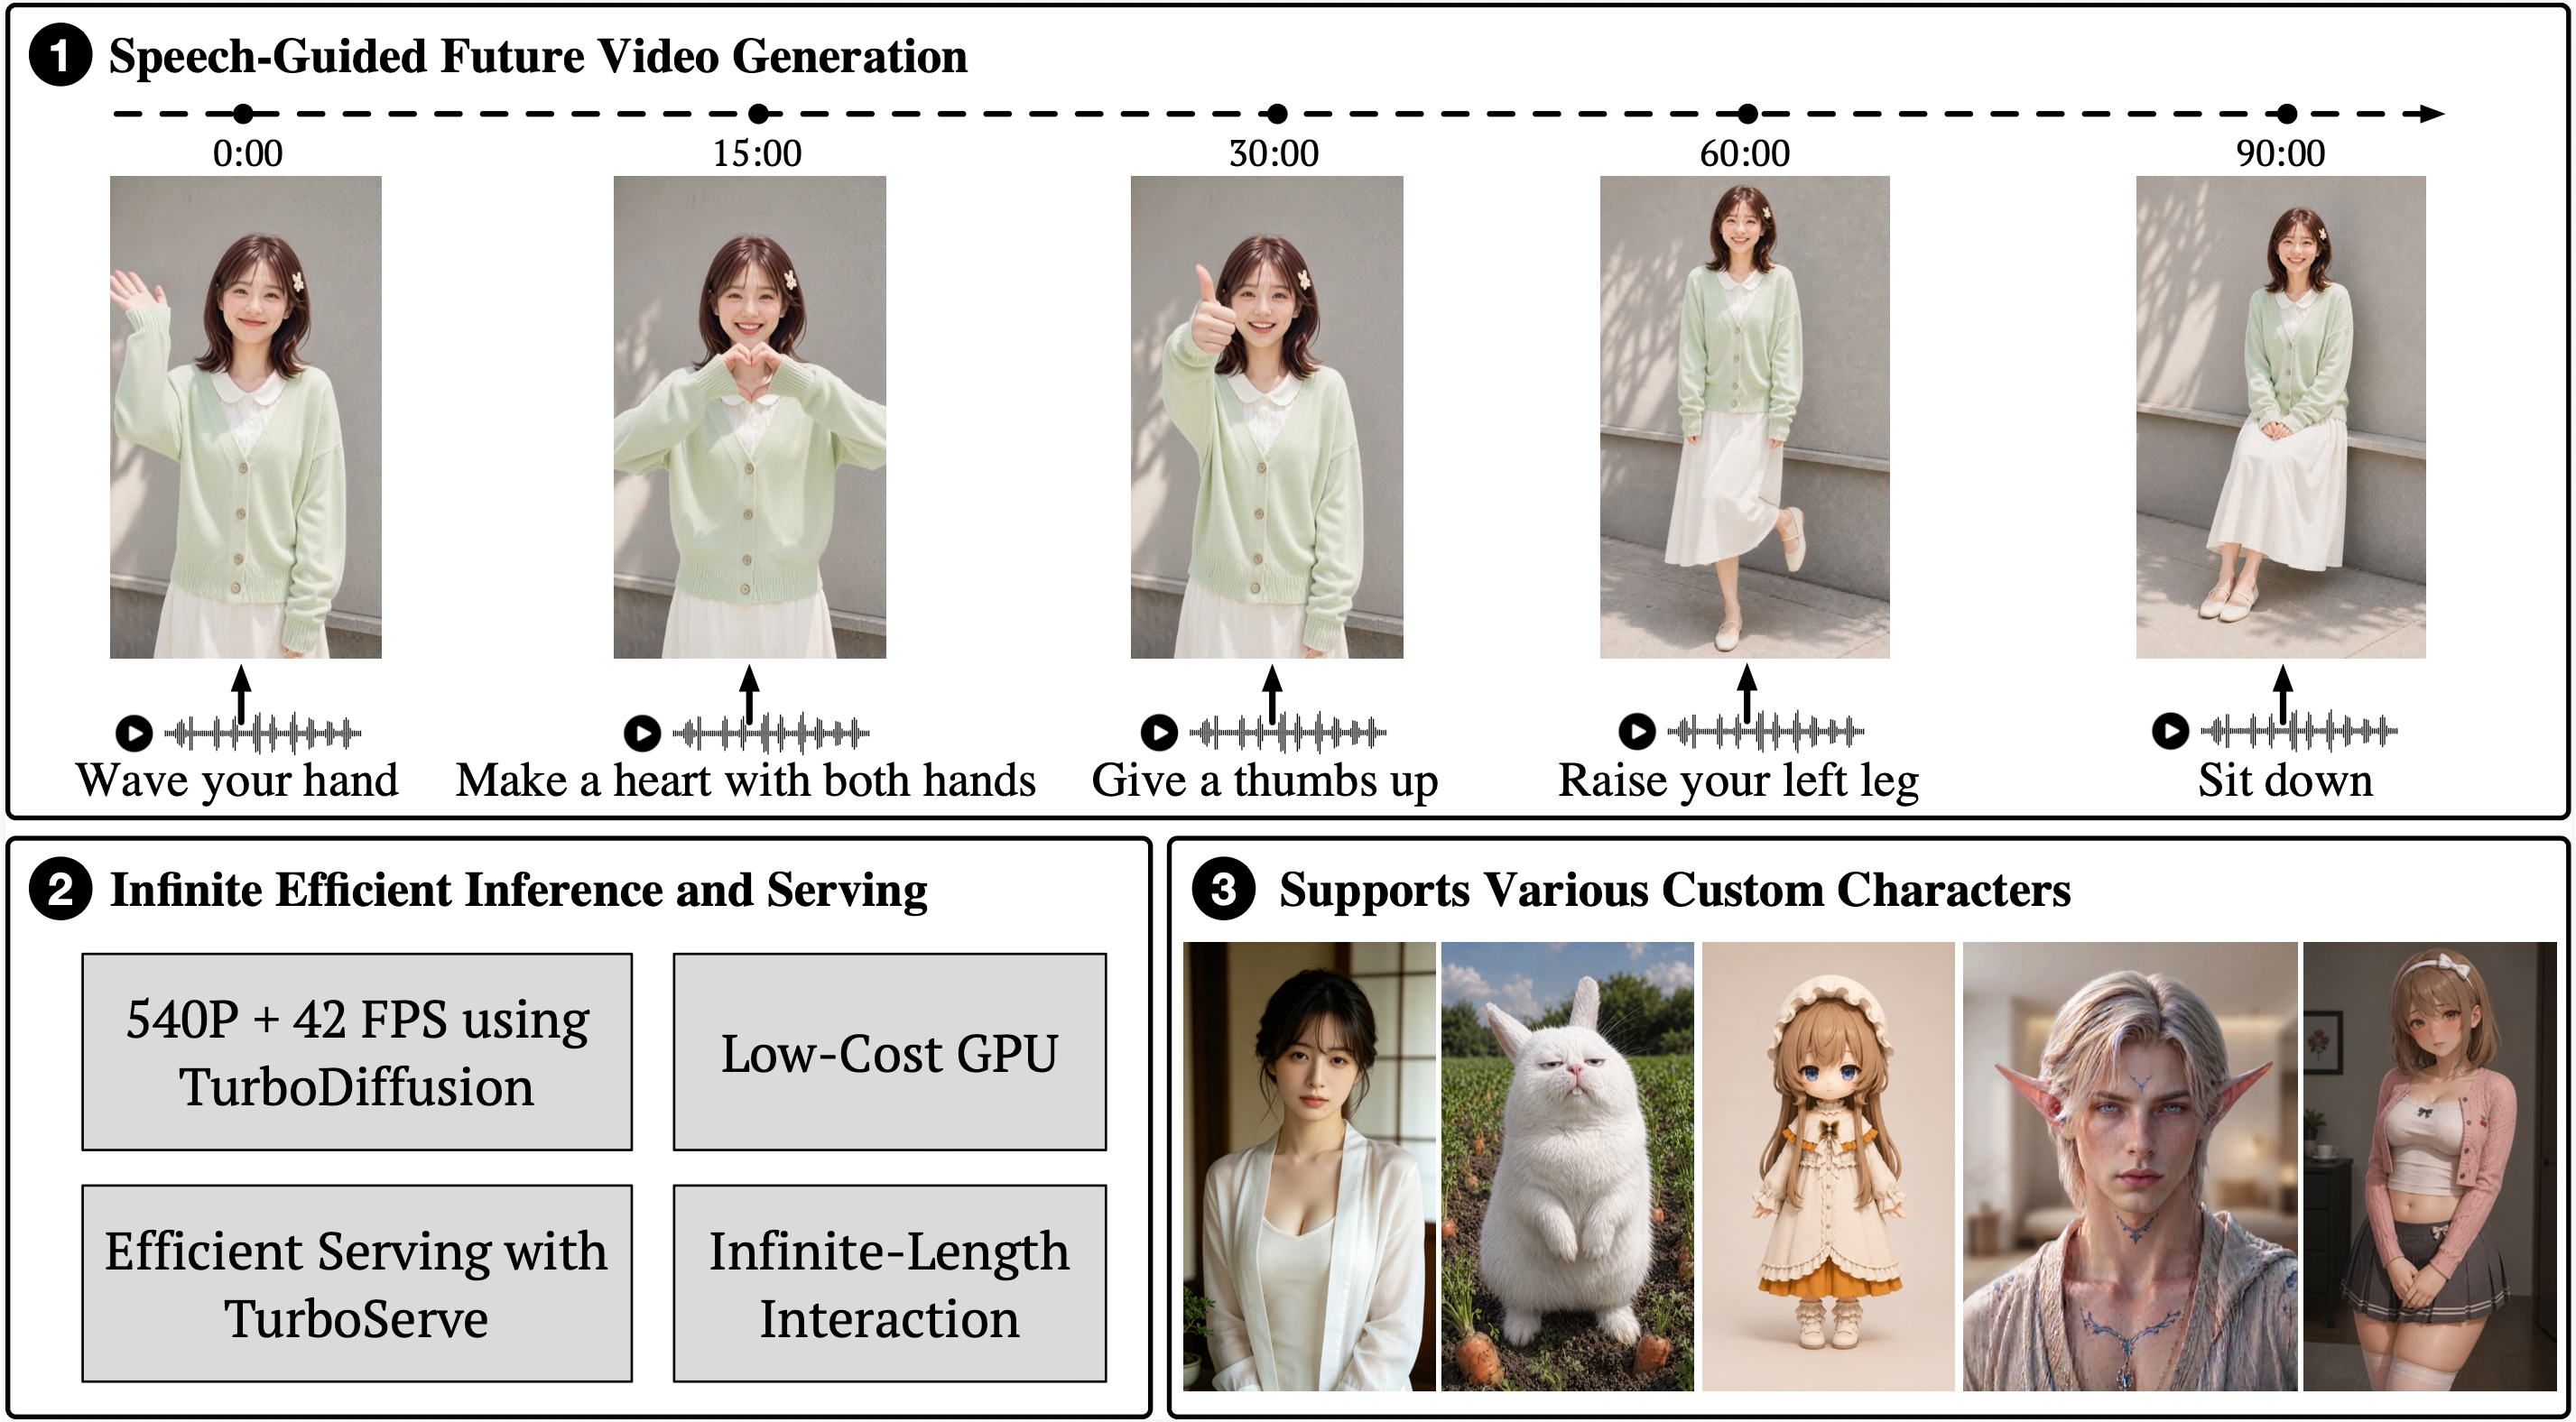
-
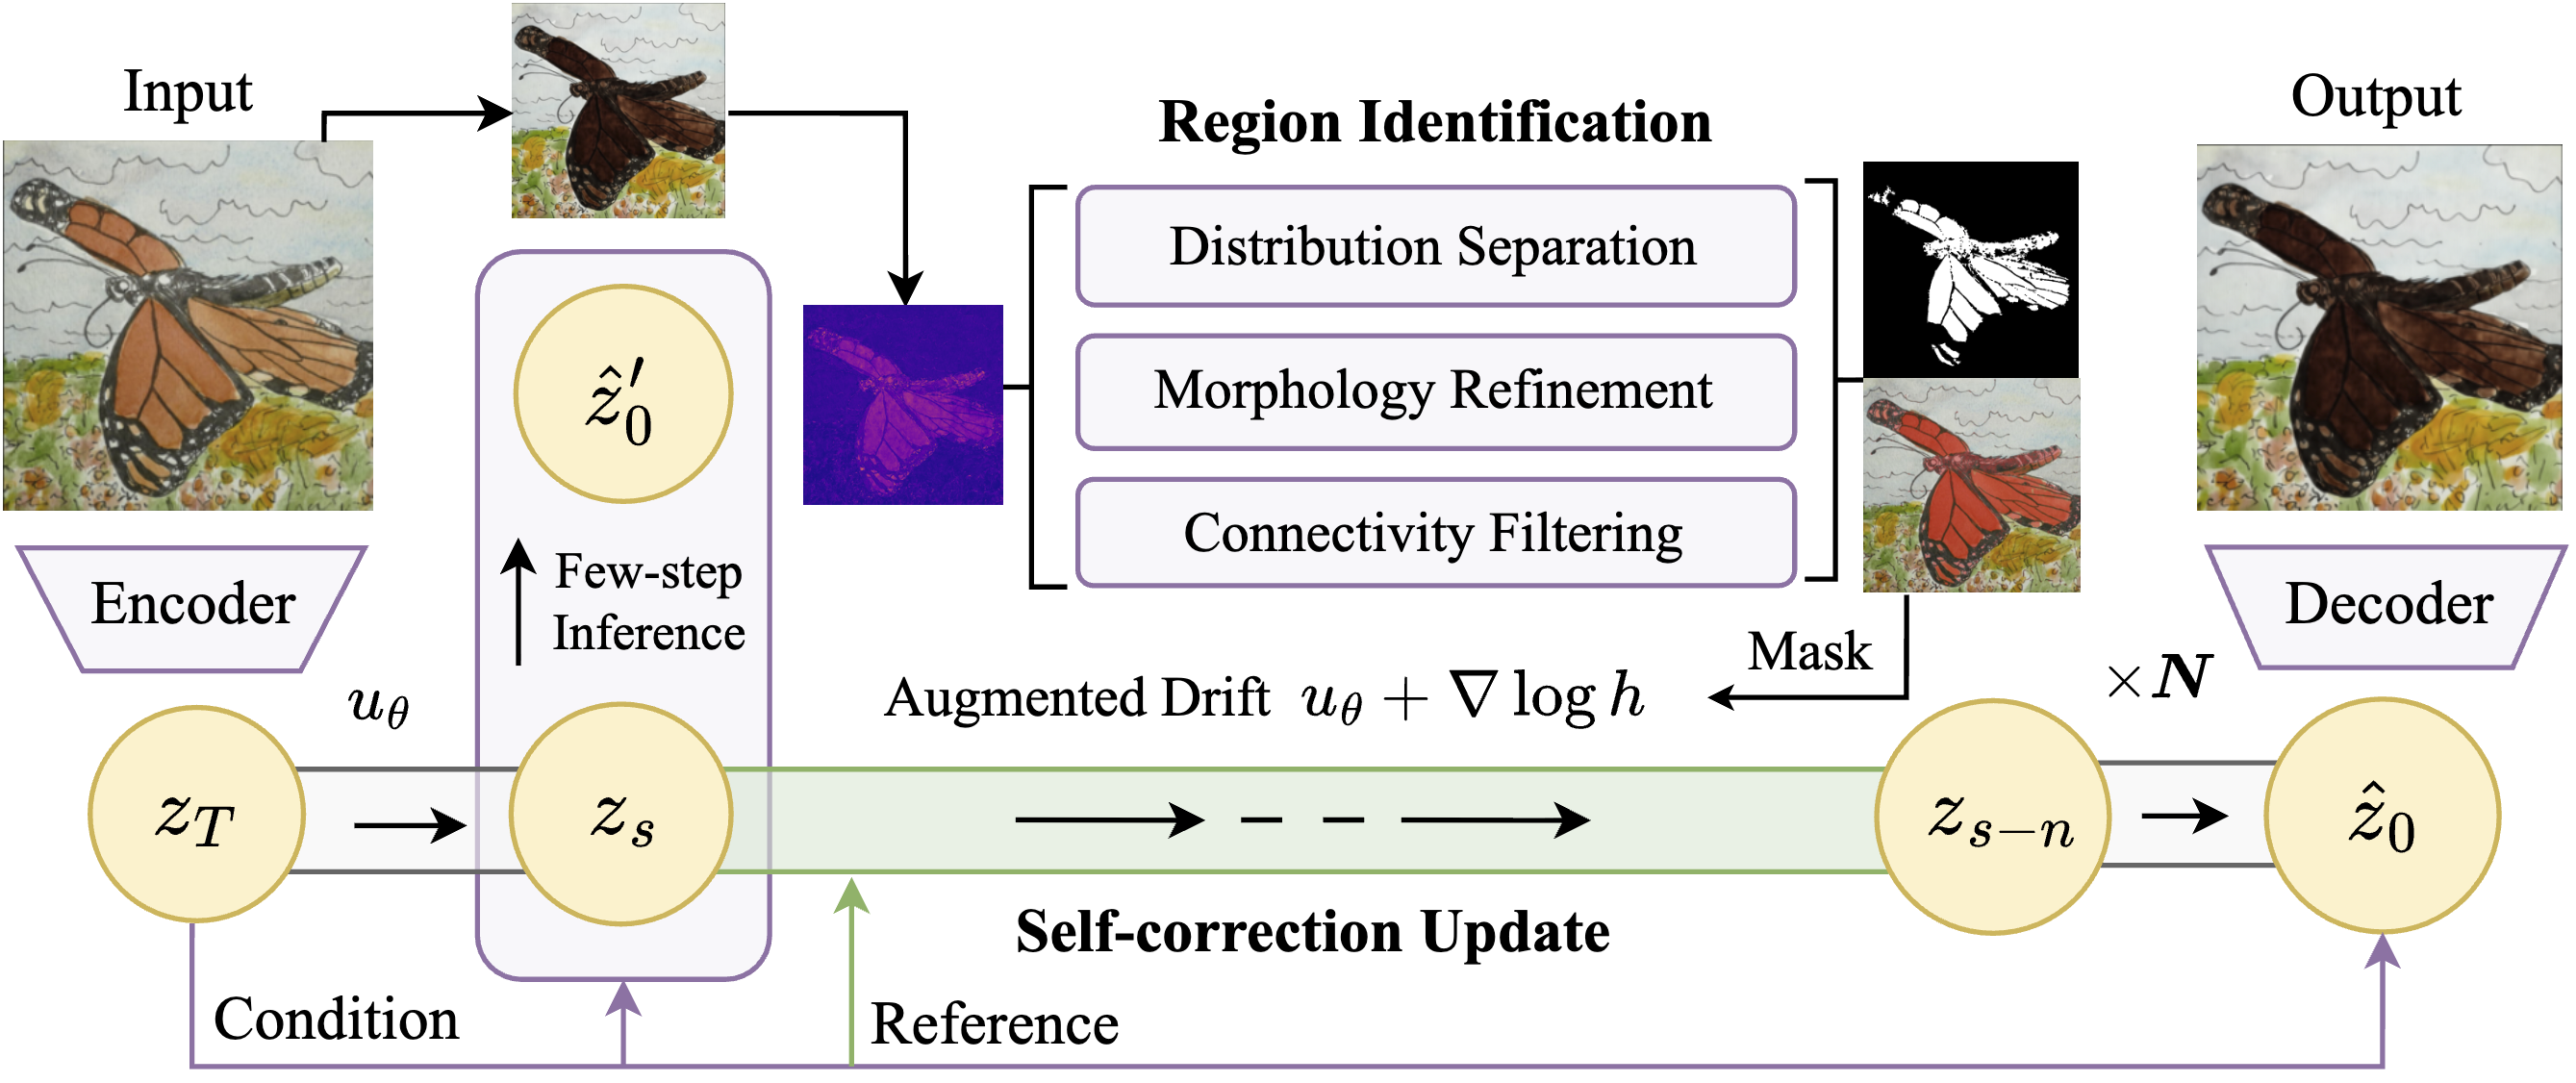 European Conference on Computer Vision (ECCV), 2026.
-
 Annual Conference of the International Speech Communication Association (INTERSPEECH), 2026.
-
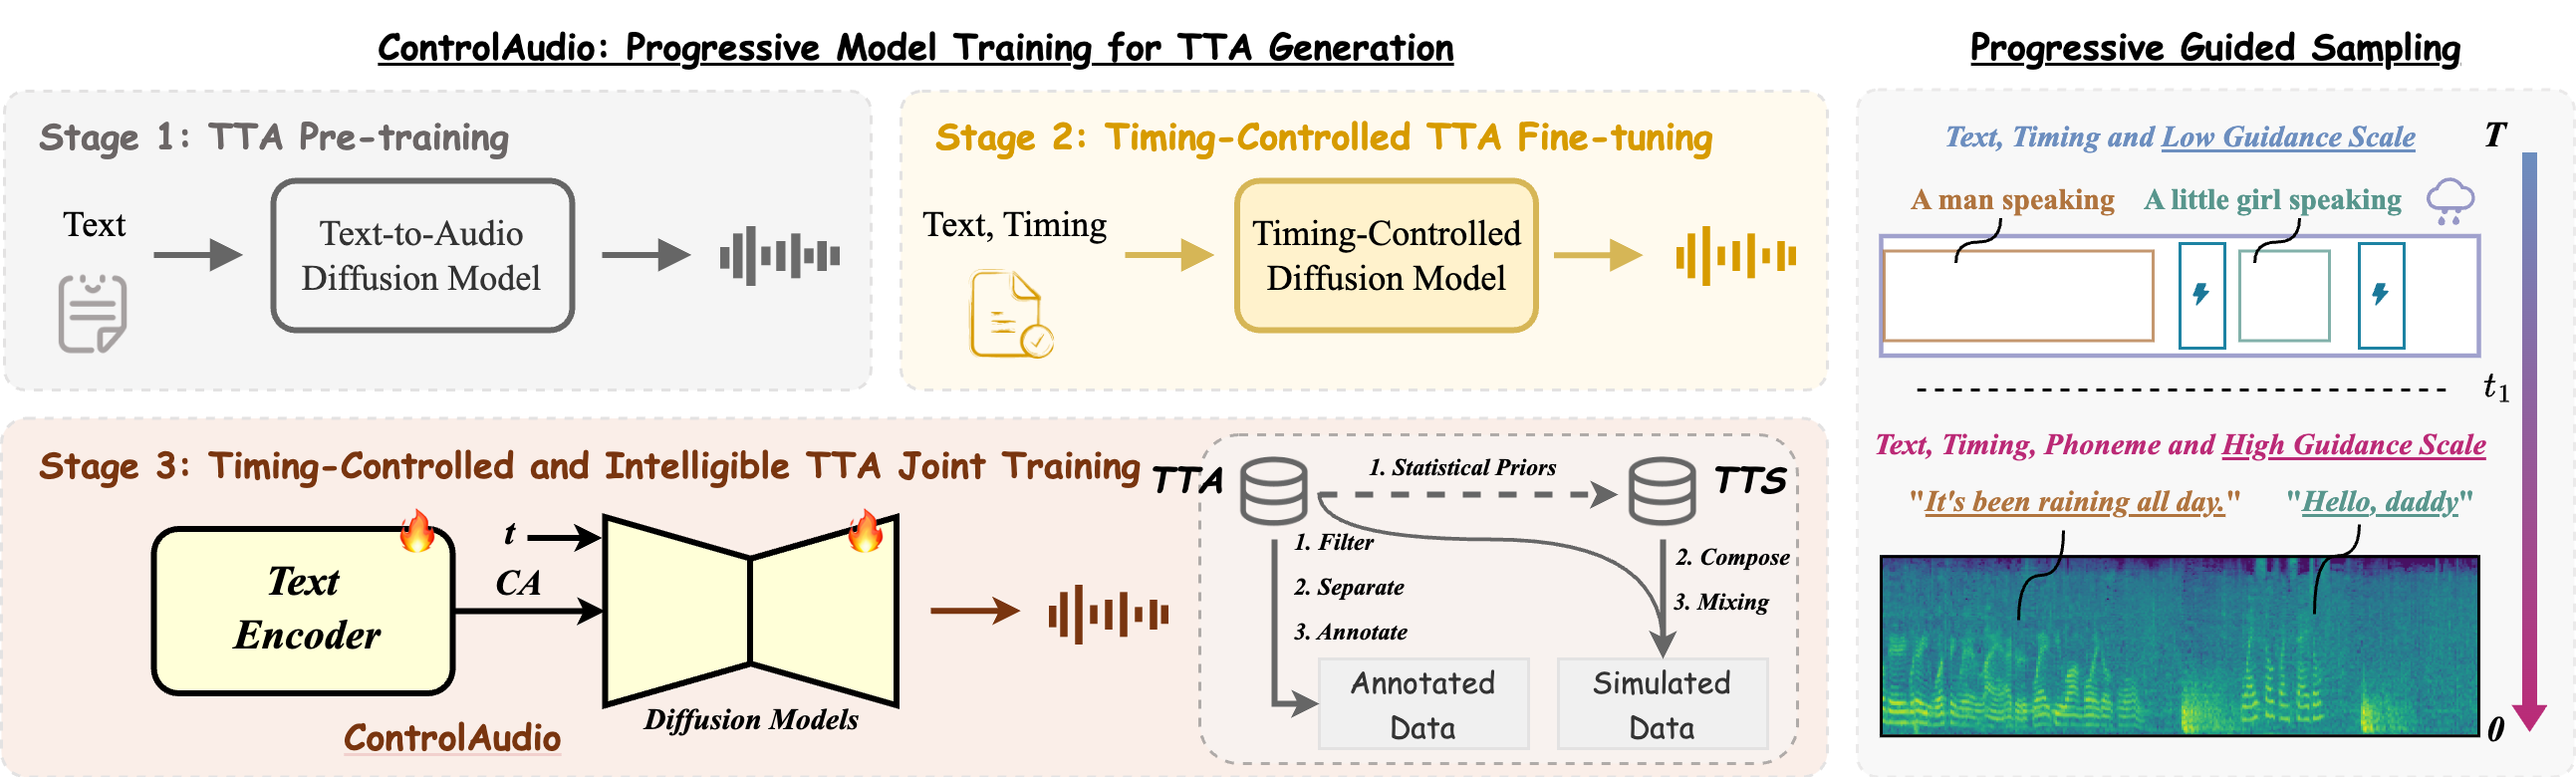 Annual Meeting of the Association for Computational Linguistics (ACL), 2026.arXiv Project Page Oral
-
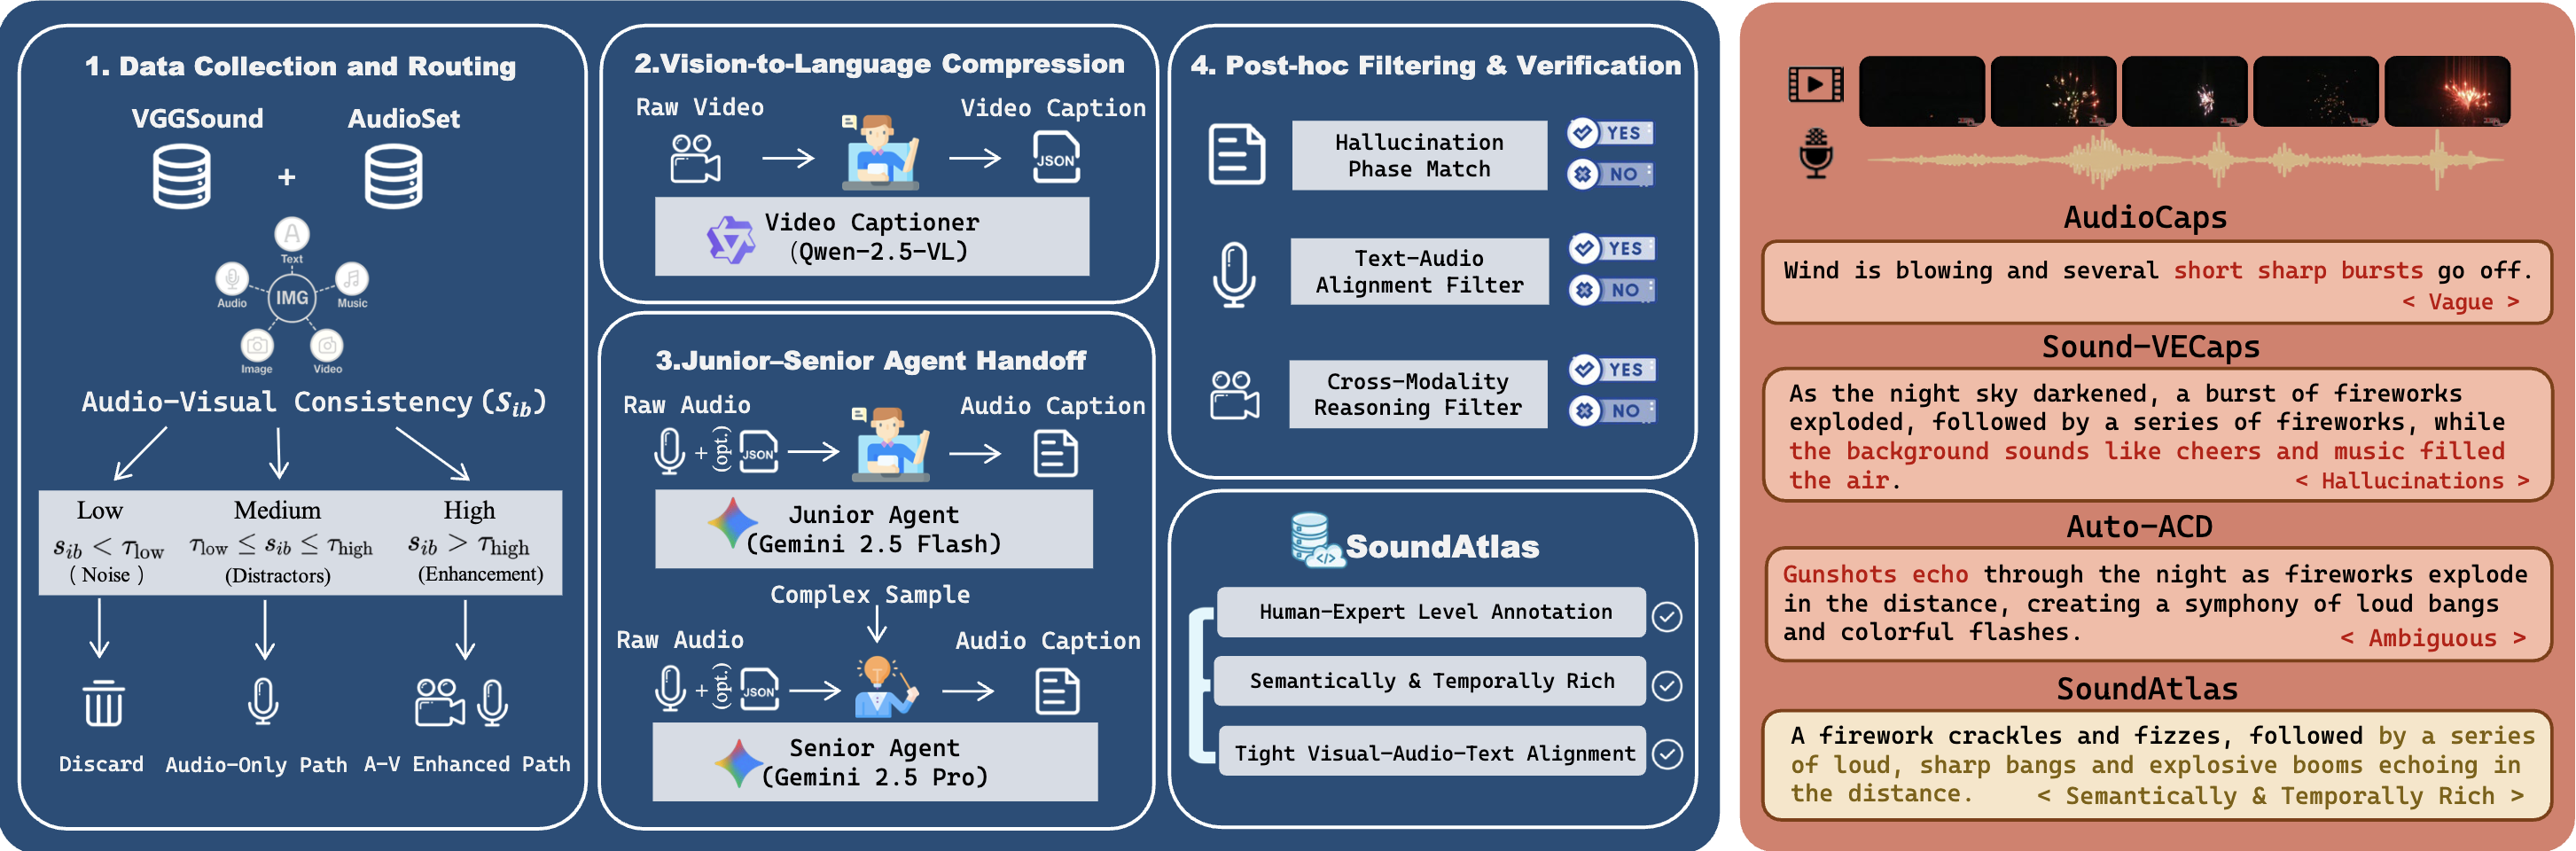 IEEE / CVF Computer Vision and Pattern Recognition Conference (CVPR), 2026.arXiv Project Page Highlight
-
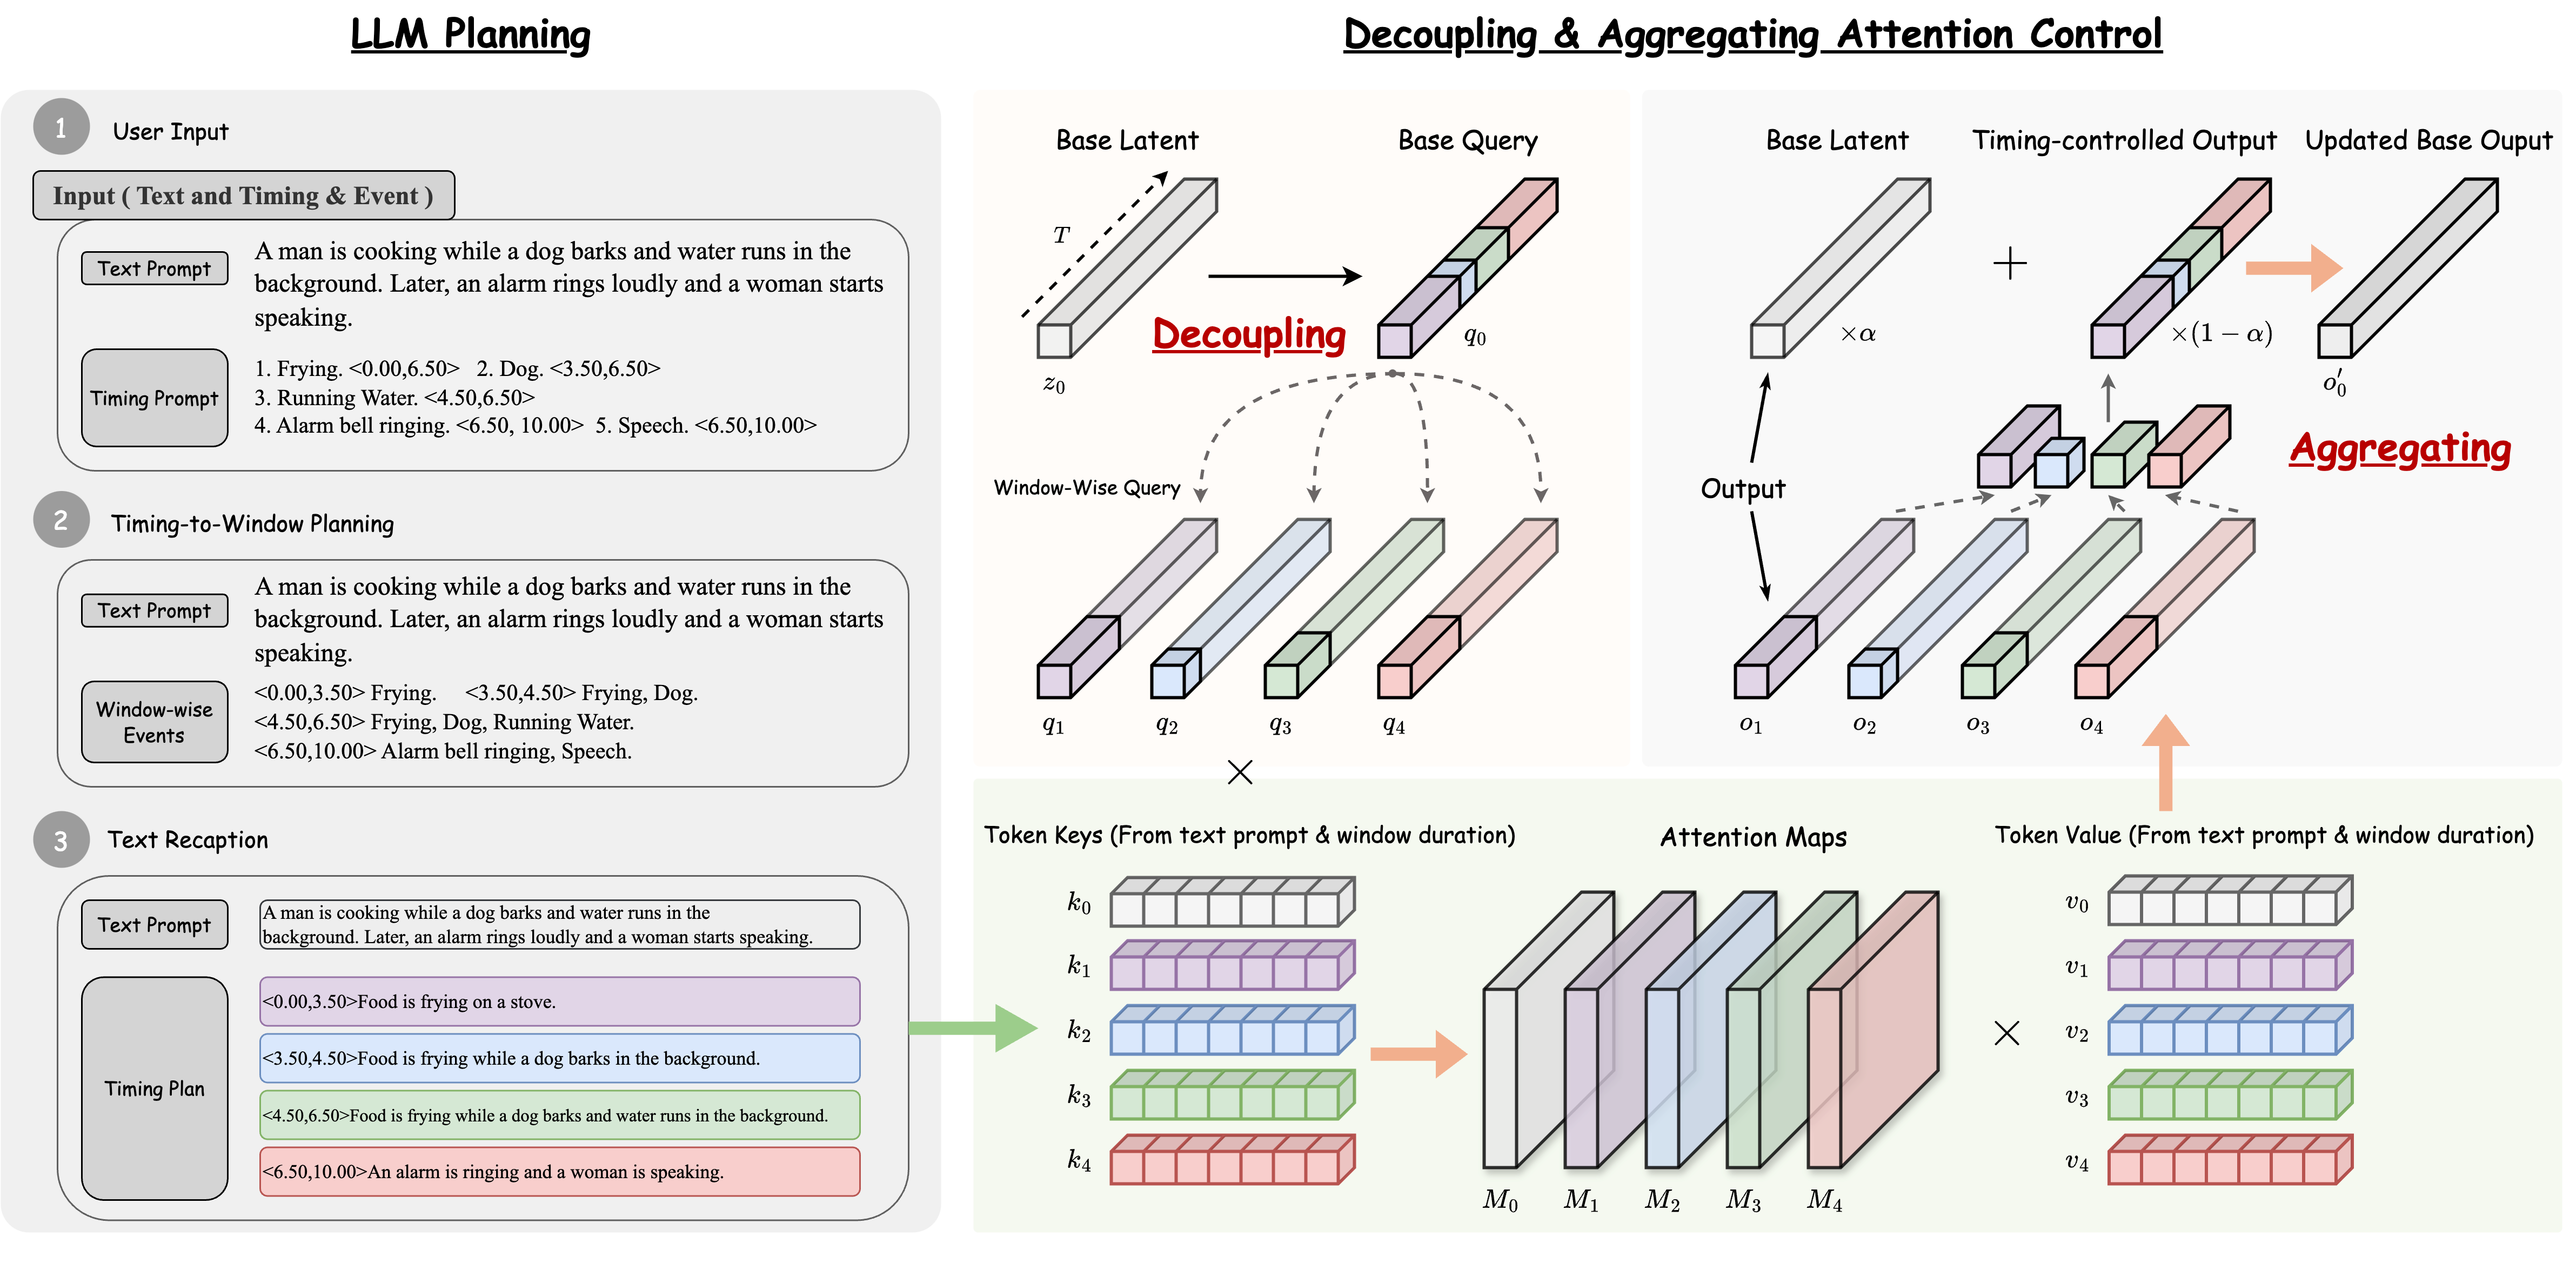 ACM International Conference on Multimedia (ACM MM), 2025.arXiv Project Page Oral
© Yuxuan Jiang, 2026